
Turn Speed
Live decode tok/s, prefill and token breakdown for every agent turn

该插件的概览尚未翻译为你的语言,因此以英文显示。
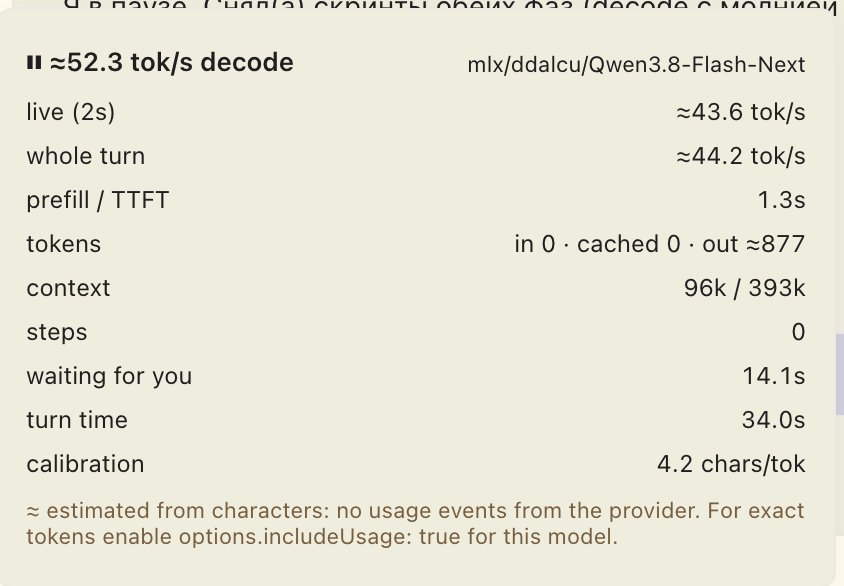
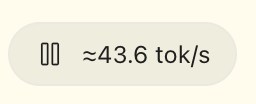
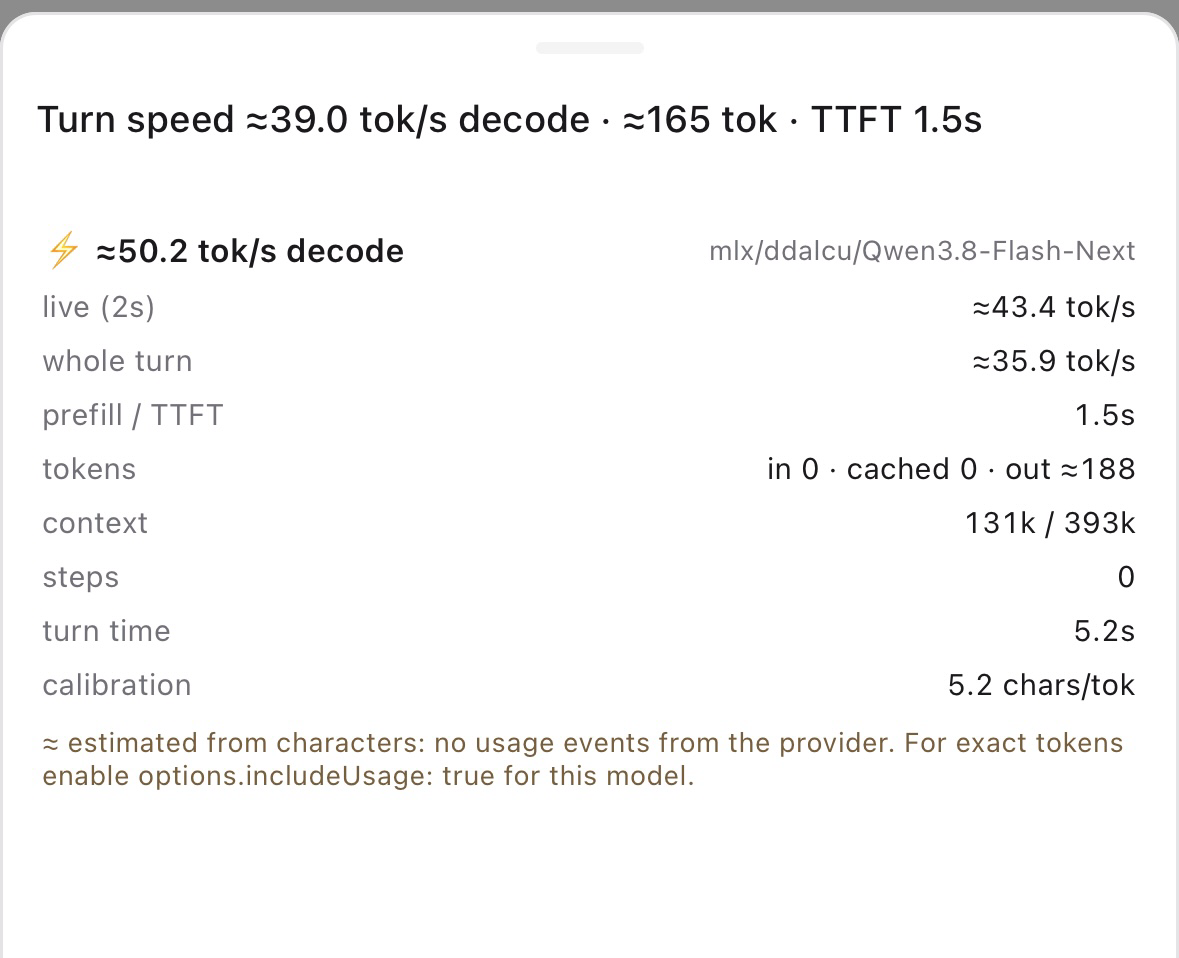
A composer pill on every agent that shows how fast the model is decoding: live tok/s while a turn runs, final tok/s and token totals after it, and a popover with the breakdown — prefill/TTFT, in/cached/out tokens, model-call steps, tool wait time, and context occupancy.
Speed is measured over decode windows only: tool waits, long pauses, and prompt
prefill are separated out, so the number reflects generation speed rather than
turn latency. When the provider reports real usage (for OpenCode/MLX models
enable options.includeUsage: true in the provider config), numbers are exact.
Without usage the plugin estimates tokens from streamed characters, marks them
with ≈, and auto-calibrates a per-model chars/token ratio from every step that
does report usage. Reasoning models whose provider subtracts thinking from the
reported output are detected automatically; their rates include an estimate of
the thinking tokens (streamed reasoning characters converted with a measured
reasoning-specific chars/token ratio), and the popover shows it as a separate
thinking ≈ line. The verdict is per model: switching models or a provider
config that starts including thinking revokes it, so nothing is double-counted.
Options live under Settings → Plugins → Turn speed: what the pill leads with
(live estimate, decode-window average, or whole-turn rate, switchable from the
popover), smoothing window for the live number, token format, idle-pill
visibility, and a manual chars/token override. Requires Paseo 0.11 or later;
see the README for installing from GitHub or npm.
Turns are observed live; history from before a plugin reload is not
reconstructed. Subagents keep their own pills, but the parent also knows about
them: time delegated to running subagents is excluded from the parent's
whole-turn rate, its pill grows a · N sub badge, and for Paseo-native child
agents the popover adds a per-subagent breakdown with a combined team rate.
Subagent replies count as the parent's input tokens, never its output.